Monday, 2 August 2021

Summer fun with Musicbrainz: the "real" Six Degrees of Kanye West (part 3/3)

So: now that we have had some fun setting up our local Musicbrainz database (part 1), and importing the data into our Neo4j database (part 2), we can now start having some fun. That means: checking if that actual 6 degrees of Kanye West, and the actual "Kanye Number", is findable and reproducible in our Neo4j database, in an efficient way. Let's take a look at that.

Note: part of this effort was actually motivated by the fact that I have noticed that the python code that powers the above website, actually caches the results (see the github repo for more info) rather than calculate the Kanye Number in real time like we will do here. I guess that speaks to the power of graph databases, right?

But let's take a look at some queries.

Find other artists that worked together with Kanye

Let's start with some simple

match (kanye:Artist {name: "Kanye West"})--(r:Recording)--(a2:Artist)
return kanye,r,a2
limit 100

That gives you a bit of a peek already: Kanye's co-recorders

Read more »

Labels: , , , , , , , , ,

Summer fun with Musicbrainz: the "real" Six Degrees of Kanye West (part 2/3)

In the first article of this series we talked about our mission to recreate the Six Degrees of Kanye West website in Neo4j - and how we are going to use the (Musicbrainz database)[www.musicbrainz.org] to do that. We have a running postgres database, and now we can start the import of part of the dataset into Neo4j to understand what the infamous Kanye Number of artists would be.

Loading data into Neo4j

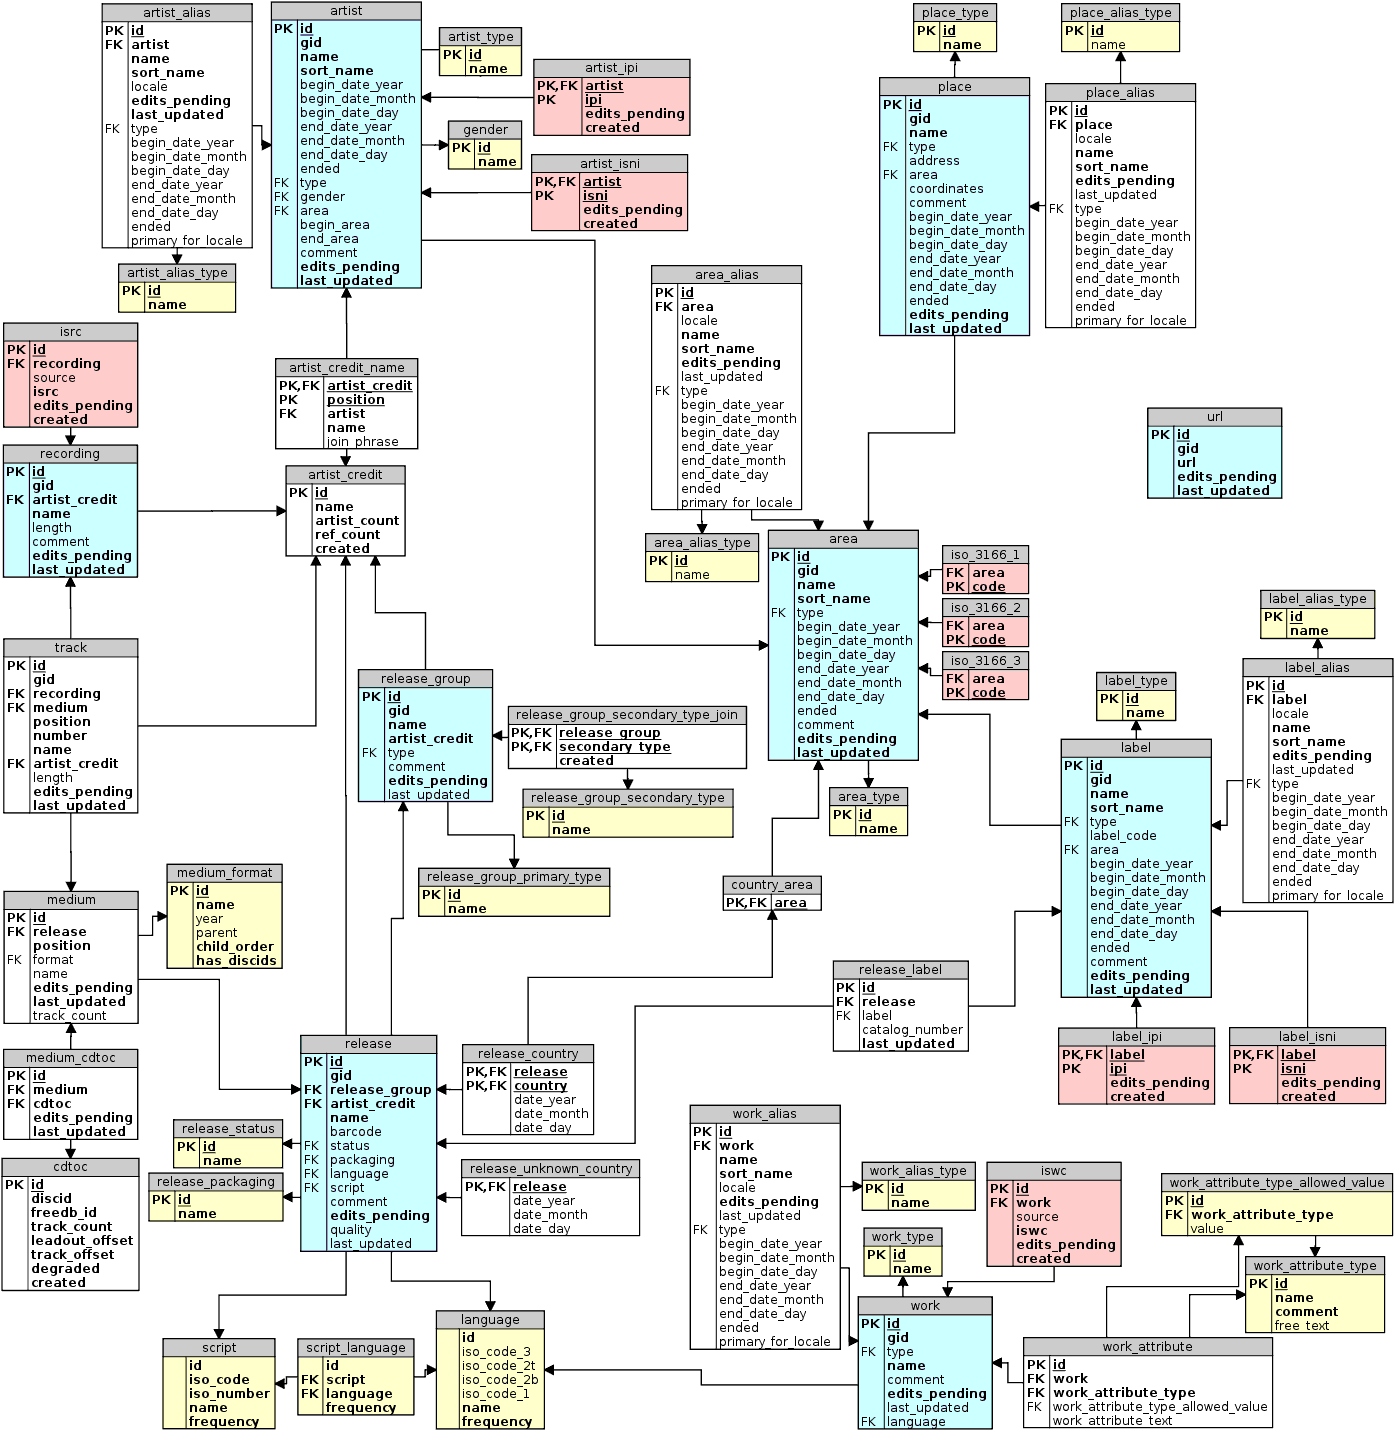
There's lots of different approaches to loadhing the data, but when I started looking at the model in a bit more detail:

  the model

Read more »

Labels: , , , , , , , , ,

Summer fun with Musicbrainz: the "real" Six Degrees of Kanye West (part 1/3)

Last year, I had a lot of fun working with a fantastic little tool that a colleague of mine created, to analyse and enhance Spotify playlists using Neo4j. While I was working on that blogpost, and I was experimenting with what little I know of Python code, I came across another example project that Spotify actually highlighted on their website: it's called Six Degrees of Kanye West and it's simply amazing.

The idea behind this site seems to be similar to the "Six Degrees of Kevin Bacon": if you have ever worked with Kevin directly, your Bacon Number is 1. If you have worked with someone that has worked with Kevin, then your Bacon Number is 2. Etc etc - and then this is applied to the idea of musicians working together on songs.

For example, if you go there and you look up some unknown artist (like then inimitable Belgian schlager singer, Helmut Lotti), like this:


Read more »

Labels: , , , , , , , , ,

Friday, 22 June 2018

Podcast Interview with Estelle Joubert, Dalhousie University

One of the coolest things about Neo4j is just the sheer breadth and diversity of applications that we see for connected data and graph databases out there. I think I have said it before, but it truly continues to baffle me. Very frequently, I will have a morning conversation with a user about battling financial fraud, a lunch conversation about using graphs in biotech to fight world hunger, and an afternoon conversation about real time recommender systems in retail. And of course finish it of with a beergraph conversation in the evening :) ...

Really - it's just amazing. And the next podcast episode is a true testimony to that. I got to have a chat with a lovely lady all the way over in Canada recently, Estelle Joubert from Dalhousie University. She and her team have been using Neo4j in her amazing field of research, which is all about understanding how music and opera came to be what they are today in a historical perspective. She is best at explaining it herself - so here's our chat:


Here's the transcript of our conversation:
RVB:  00:01:20.209 Hello, everyone. My name is Rik, Rik Van Bruggen from Neo4J, and tonight I am joined by a guest on our podcast all the way from Canada, someone that has been working with, and experimenting with, Neo4j for quite some time in a very interesting domain that I hadn't heard of before. And that's Estelle Joubert from Dalhousie University. Hi, Estelle.

Read more »

Labels: , , , , , , , , , , ,

Wednesday, 24 February 2016

What's a graph without a laugh? Multi-lingual Graph Karaoke is HERE!

Indeed. If you follow this blog and some of my work with Neo4j a little bit, then I am hoping you know that I like to have FUN with Neo4j as well. It's actually quite amazing that you CAN in fact have fun with something as "boring" as a database - but hey, I really think you can.

I have been doing Graph Karaoke for a long time (I still blame Nigel) - and that has been a ton of fun along the way. Over the years, I gathered quite a playlist:
And now with GraphConnect Europe coming up in April, I felt like we would really need some more songs to spice up the conference. But: being in Europe - WHY would we limit ourselves to boring ENGLISH songs all the time. So I figured, there has to be a way to do Graph Karaoke in a multi-lingual way. And that's what I will be doing in the next few months - and today is the first episode in "MultiLingual Graph Karaoke".

Google Sheets to the rescue!

We'll start with a nice little Dutch song that I really like, by the world-famous (!) group "Doe Maar!". The song is "Dansmuziek", and has a lovely vibe to it, I think.

I grabbed the lyrics online, and put it in a google spreadsheet. It looks like this:
As you can see (access the sheet yourself over here), I have one column in there with the lyrics in the original, Dutch language, but I also have a couple of other columns that are automatically translated into English, German and French using the Googletranslate function of Google Sheets. I simply do:

=GOOGLETRANSLATE(C2,"nl","en")
=GOOGLETRANSLATE(C2,"nl","fr")
=GOOGLETRANSLATE(C2,"nl","de")


and these lyrics get automatically translated into the other languages. Obviously the translations will not be perfect, but hey, at least you get to do multi-lingual graph karaoke then! Yey!

Once I have this, I can download the spreadsheet as a CSV file, and then I can start working with it in Cypher. I have created an Import gist on Github - so you can basically run it yourself and import the graph at your own convenience.

Creating the Karaoke video

Once we have that, it's child's play to actually create the Karaoke video. A few very simple queries suffice:

match (w:Dutch {seq:1})
return w;


to find a sentence in a specific language. Or

match (w {seq:1})
return w;


to find a sentence in any language. And then finally also a "tabular" representation that would be easy to read:

match (w {seq:4})
where not ("SongSentence"in labels(w))
return w.seq as Sequence, labels(w) as Language, collect(w.name) as Sentence
order by Language[0]


All of that then brings me to the following - slightly stupid, I agree - slightly wonderful result:


That's it! I plan make a few more of these before GraphConnect, and publish them here as well. If you have any "song requests" in your own language, then PLEASE let me know.

Cheers

Rik

Labels: , , , , , , , , ,

Wednesday, 14 October 2015

Stockholm meetup got a bit out of hand

Tonight we had a lovely meetup in lovely Stockholm at our friends of HiQ. They have a wonderful office and event area overlooking downtown Stockholm, a perfect setting to sit back and talk graphs. So we did. My friend and colleague David Montag did a wonderful talk, and I tried to tell people how to really NOT mess up their Neo4j project. The presentation is over here:

But somewhere along the way, I also started talking about my lack of a social life (so sad!!!) and the fact that I have a bit of fun with graph karaoke. I know - it's stupid. But so about half an hour before my talk, someone says "Can you do that for "Roxanne"?" ... and I am like - being a big Police fan and all - alright, Challenge Accepted.

So here's what I did:
  • I grabbed the lyrics from AZLyrics
  • I put it into this google sheet.
  • I made the google sheet available to the public (important).
  • I downloaded that sheet as a CSV file, and grabbed the URL from my downloads folder.
  • and then ran this cypher query over it:
 load csv with headers from "https://docs.google.com/a/neotechnology.com/spreadsheets/d/1WK-AKp-KNegaQ5-hbS79wvaNEj_SDj971iCuX9GMDSo/export?format=csv&id=1WK-AKp-KNegaQ5-hbS79wvaNEj_SDj971iCuX9GMDSo&gid=0" as csv  
 with csv.Sequence as seq, csv.Songsentence as row  
 unwind row as text  
 with seq, reduce(t=tolower(text), delim in [",",".","!","?",'"',":",";","'","-"] | replace(t,delim,"")) as normalized  
 with seq, [w in split(normalized," ") | trim(w)] as words  
 unwind range(0,size(words)-2) as idx  
 MERGE (w1:Word {name:words[idx], seq:toInt(seq)})  
 MERGE (w2:Word {name:words[idx+1], seq:toInt(seq)})  
 MERGE (w1)-[r:NEXT {seq:toInt(seq)}]->(w2)  

And that's it. Graph is ready. Next I find the song in Spotify, play it a few times to rehearse, and then we get this:


So there you go. I hope you enjoyed it as much as I did. And don't forget to register for GraphConnect next week!!!

Cheers

Rik

Labels: , , , , ,

Thursday, 29 May 2014

Dem-O Bones

** UPDATE: I wrote a GraphGist to complement this post as well.

I had so much fun at the Graph Pub tonight in London. It was amazing. Lots of wonderful talks there, and I got to finish it of with my personal Graph Playlist and a LIVE! demo of Dem Bones. Graphs are awesome, and Graphs About Music are even more awesome, at least in my book.

So here is the Graph Playlist for you to contribute to:


Please add it to your Spotify account, if you have one, and start adding songs. Would not mind a #graphplaylist tweet if you do!

Then of course, there was my interpretation of Dem Bones, in a Neo4j database. Here's a little video of it:


You can create the dataset yourself using this gist, and you can query it using the queries in this gist over here. 

Hope you like this as much as I enjoyed creating it.

Cheers

Rik


Labels: , , , ,

Tuesday, 15 October 2013

Importing my Last.fm dataset - the neo4j way

Some time ago, I blogged about how you could create an interesting graph dataset in neo4j using the data from Last.fm. At the time, I used Talend as an ETL tool, to do the import into neo4j – as the dataset was quite large and the spreadsheet method would probably not cut it anymore. It worked great – the only downside (for this particular use case) was that ... I had to learn Talend. And not that that is terribly difficult – especially not if you are an experienced ETL professional, which I am clearly NOT – but there was definitely a learning curve involved. So: there continued to be a latent desire to do this import into neo4j natively – without separate tooling. And now, I think we have that, thanks to the ever-amazing Michael Hunger.

Enter neo4j-shell-tools

Michael created a collection of utilities that basically plug into the neo4j-shell, and extend its functionalities with things like... data import functionalities. There are different options, and you should definitely read up on the different capabilities, but for my specific Last.fm use case, what was important was that it can easily import the csv files that I had created at the time for the import using talend.

You can read up on the details of the shell-tools in the readme (in contains very simple installation instructions that you would need to go through beforehand – essentially installing the .jar file in neo4j's lib directory). Once you have done that and you shutdown/restart the neo4j server, you are good to go.

Creating the database from scratch.

As you will see below, the steps are quite simple:

Step 1: start with an empty neo4j database

What's important here is that the neo4j-shell-tools work on a **running** neo4j database. You do not need to introduce downtime, and you do not use the so-called “batchimporter” method – instead you are doing a full blow, transactional, live update on the graph, using this toolset.

Step 2: prepare the .csv files

I had already prepared these files for the previous blogpost – so that was easy. The only difference that I had to make was that I
  • had to make sure that the delimiter that I was using was right. The neo4j-shell-tool allows you to specify the type of delimiter, and getting that wrong will obviously lead to faulty imports
  • had to add a “header” row at the top of the text files. The neo4j-shell-tool will assume that the first line of the .csv files defines the structure of the rest of the file. Which also then means, that I needed multiple files as both the nodes and relationships that I wanted to add have a different structure/type.
So I ended up with 2 .csv files to add nodes to the graph, and 7 .csv files to add the relationships between the nodes. You can download everything here.

Step 3: prepare the import commands

The node import commands look like this

import-cypher -d ; -i nodespart1.csv -o 1out.csv create (n{name:{name}, type:{type}}) return n.name as name

import-cypher -d ; -i nodespart2.csv -o 2out.csv create (n{title:{title}, name:{name}, type:{type}}) return n.name as name

The structure of these commands is fairly simple:
  • import-cypher: calls the shell tool that we want to use
  • -d defines the delimiter of the file that we are importing. In these case a “;”.
  • -i defines the input file. On OSX, not adding a path will just look for the file in the root of your neo4j installation directory. In many cases you will want to have an absolute, or relative path from there.
  • -o defines an option output file where the result of the import commands will be written. This is intended for logging purposes.
  • And then finally, with the highlighted “create...” section, we basically define the Cypher query that will do the import transaction – using the parameters from the csv file (between { }) as input.
Note that the neo4j-shell-tools provide some separate functionalities for dealing with large input files and for tuning the transaction throttling (how many updates in one transaction), but that for this purpose we really did not need to do that.

Then for the relationship import commands, we have a very similar structure:

import-cypher -d ; -i APPEARS_ON.csv -o 3out.csv start n1=node:node_auto_index(name={mbid1}), n2=node:node_auto_index(name={mbid2}) create unique n1-[:APPEARS_ON]->n2 return n1.name, n2.name

import-cypher -d ; -i CREATES.csv -o 4out.csv start n1=node:node_auto_index(name={mbid1}), n2=node:node_auto_index(name={mbid2}) create unique n1-[:CREATES]->n2 return n1.name, n2.name

import-cypher -d ; -i FEATURES.csv -o 5out.csv start n1=node:node_auto_index(name={scrobble}), n2=node:node_auto_index(name={mbid}) create unique n1-[:FEATURES]->n2 return n1.name, n2.name

import-cypher -d ; -i LOGS.csv -o 6out.csv start n1=node:node_auto_index(name={user}), n2=node:node_auto_index(name={song}) create n1-[:LOGS]->n2 return n1.name, n2.name

import-cypher -d ; -i ON_DATE.csv -o 7out.csv start n1=node:node_auto_index(name={scrobble}), n2=node:node_auto_index(name={date}) create n1-[:ON_DATE]->n2 return n1.name, n2.name

import-cypher -d ; -i PERFORMS.csv -o 8out.csv start n1=node:node_auto_index(name={mbid1}), n2=node:node_auto_index(name={mbid2}) create unique n1-[:PERFORMS]->n2 return n1.name, n2.name

import-cypher -d ; -i PRECEDES.csv -o 9out.csv start n1=node:node_auto_index(name={date1}), n2=node:node_auto_index(name={date2}) create n1-[:PRECEDES]->n2 return n1.name, n2.name

Note that, because of the domain model that we have from the last.fm dataset, some relationships have to be unique and others don't – hence the difference in the Cypher queries.

Step 4: executing the commands

Then all we need to do is to put the files on the right locations, make sure that autoindexing is correctly defined, and then copy/paste the commands into the neo4j-shell.
On my MacBook Pro, the entire import took about 35 seconds, and I ended up with the database that I had previously created with the Talend toolset:

And then the same graphic/query exploration can begin. You can take the graphical tools for a spin, or alternatively create your own cypher queries and get going.

Conclusion

Overall, I found this new process to be extremely intuitive and straightforward – even simpler then what I had experienced using the Talend toolset. I have put the zip-file and the corresponding input statements over here – so feel to download and experiment yourself. Just make sure that you put the .csv files in the neo4j “home directory”, or adjust the paths as you want (both relative and absolute paths seemed to work on my machine).

Hope this was useful. Until the next time!


Rik

Labels: , , , ,